Do I have to label all AI-generated content?
The short answer is no, but the correct answer requires distinguishing who labels, what is labelled, and towards whom. Article 50 of Regulation (EU) 2024/1689 on Artificial Intelligence (the “AI Act”) governs this obligation independently of the system’s risk classification: a chatbot classified as minimal risk may be subject to a transparency duty that another system is not. Conflating “not high-risk” with “no labelling required” is, by far, the most common compliance error we encounter when auditing AI-generated content.
What content must be labelled
Article 50 of the AI Act sets out four distinct scenarios that should not be conflated, as they have different addressees and scope.
The first applies to any provider of an AI system intended to interact directly with natural persons: it must be ensured that the user is aware they are interacting with a machine, unless this is obvious from the circumstances. This covers chatbots, voice assistants and conversational agents, regardless of their risk tier.
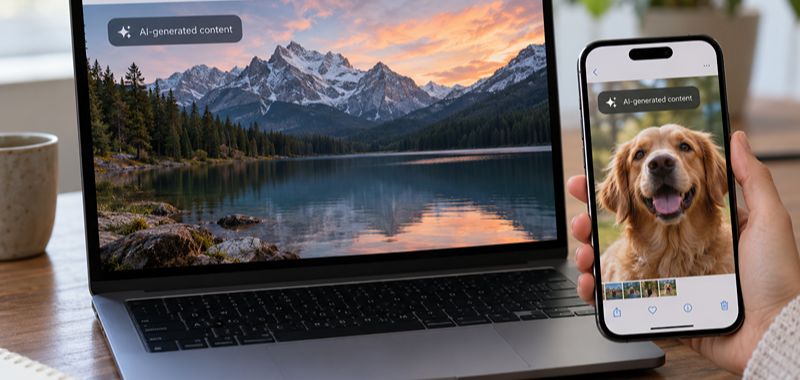
The second is the marking obligation proper: the provider of a system generating synthetic audio, image, video or text content must ensure that output is marked in a machine-readable format and detectable as artificially generated or manipulated. This is the least flexible of the four obligations, and it rests on the provider of the system, not on the party using it.
The third applies to deployers of content constituting a deep fake: image, audio or video content resembling existing persons, objects, places or events that would falsely appear to a person to be authentic. Here the duty to disclose that the content is artificial rests on whoever publishes or distributes it, not on the developer of the underlying model.
The fourth concerns specifically text generated or manipulated by AI and published for the purpose of informing the public on matters of public interest: the deployer must disclose that the text has been artificially generated or manipulated.
Exemptions from labelling
This is where marketing and communications teams most often go wrong, by treating the four obligations above as if they shared a single exemption regime. They do not.
The provider’s marking obligation (the second scenario) allows for almost no exemptions: the Regulation only excuses it where the AI system performs an assistive function for standard editing without substantially altering the input data or its semantics, or where the marking is authorised by law for the purposes of detecting, preventing, investigating or prosecuting criminal offences. Outside these two scenarios, there is no exemption on the grounds that the content is minimal risk, nor by virtue of a generic legal disclaimer on a website.
The disclosure obligation for text of public interest (the fourth scenario) does carry a relevant exemption: disclosure is not required where the content has undergone a process of human review or editorial control, and a natural or legal person holds editorial responsibility for its publication. This exemption requires the ability to evidence, not merely assert, that such effective editorial review actually took place.
Deep fakes carry an exemption where they form part of an evidently artistic, creative, satirical or fictional work, provided that disclosure of their artificial nature does not impair the presentation or enjoyment of the work; and, as with marking, an exemption also applies where the use is authorised by law for the detection or prosecution of criminal offences.
How to label without getting it wrong
The first practical step is to identify, for each type of content the organisation generates or distributes, whether it is acting as the provider of the AI system, as the deployer, or as both. It is not uncommon for the same company to be the provider of its own conversational assistant and, at the same time, the deployer of content generated with third-party tools for its blog or social media; each role triggers a different obligation.
The second is to distinguish technical marking (machine-readable, embedded at the point of generation, incumbent on the provider) from disclosure to the audience (clear, visible and timely, incumbent on the deployer). These are two separate layers of compliance and one does not substitute for the other: content may carry a technical mark invisible to the average user and still require an explicit, perceptible notice within the content itself.
It is also worth bearing in mind that the harmonised standard for technical marking has been deferred by the Digital Omnibus Package to 2 December 2026, but the substantive transparency duty under Article 50 has already been enforceable since 2 August 2026: the absence of a technical standard does not suspend the underlying obligation.
Finally, documentation matters as much as labelling itself. A party seeking to rely on the editorial-review exemption must be able to show an approval workflow with an identified person responsible, and a party distributing third-party content must verify, contractually, whether the provider already incorporates the required marking: liability does not disappear through de facto delegation.
At Letslaw, we help companies that generate or distribute AI-assisted content map these four obligations onto their own production workflows and build the documentary record each exemption requires, before an inspection or a claim demands it of them.
Candela Martín es abogada especialista en derecho digital, propiedad intelectual y protección de datos.
Graduada en Derecho por la Universidad de Granada, completó un doble máster en acceso a la abogacía y derecho digital en la Universidad de Navarra. Su práctica se centra en privacidad, comercio electrónico y contratación, con una visión proactiva y resolutiva en el asesoramiento a empresas del entorno tecnológico.
More from my site
 El Mecenazgo Tecnológico como vehículo de inversión
 Compilance Officer: Todo lo que necesitas saber
 Defensa legal ante sanciones RGPD
 Más allá de las huellas dactilares: La retina como identificación biométrica en un mundo dominado por la IA
 ¿Los modelos IA son plagio o síntesis? ¿Qué opina el Tribunal de Nueva York sobre la inteligencia artificial y los derechos de autor?
 Pharmaceutical companies fined for using the Meta pixel